Approach to 64-class semantic segmentation on the GOOSE dataset. Final test score: 63.8 % composite mIoU on the ICRA 2026 Field Robotics Workshop Challenge.
Overview
The GOOSE (German Outdoor and Offroad Dataset) and its extension GOOSE-Ex contain images from three robotic platforms in unstructured outdoor environments. The task is pixel-level classification into 64 classes. Some classes are common (car, road, sky). Others are narrow (tree_root, barrel, kick_scooter). A few barely exist in the data.
Two model architectures, three augmentation strategies, test-time augmentation, and a greedy rule-learning ensemble are included. The repo contains training scripts, logs, and visualizations.
The data
GOOSE dataset splits below:
| Split | Images | Labels | Camera |
|---|---|---|---|
| goose_2d_train | ~24,000 | yes | windshield_vis |
| goose_2d_val | ~556 | yes | windshield_vis |
| gooseEx_2d_train | ~4,500 | yes | camera_left |
| gooseEx_2d_val | ~192 | yes | camera_left |
| Test set | ~361 | no | both |
Labels are grayscale PNGs where pixel value = class ID (0..63). Class 0 is undefined and counts toward metrics. No ignore index.
Class imbalance
Class imbalance is the top challenge. forest alone covers 20.7 % of all pixels. sky, asphalt, and low_grass together add another 36 %. Meanwhile pipe has roughly 1,852 pixels across the entire training set. barrel has 1,199. Several classes are so rare that models never learn them.

Rare class anatomy
Patches for the worst-performing classes (kick_scooter, barrier_tape, pipe, tree_root, motorcycle) are shown below. Most are tiny, occluded, or poorly lit.

Methods
Models
Model 1: UPerHead with FlashInternImage-L (DCNv4 backbone)
FlashInternImage-L uses deformable convolutions v4. The UPerHead decoder fuses pyramid pooling with FPN-style features. An auxiliary FCN head on stage 3 provides extra gradient flow.
- Backbone channels: 160, depths [5, 5, 22, 5]
- Pretrained on ImageNet-22K → 1K at 384×384
- Crop size: 2048×1024
- Batch size: 2
- 200,000 iterations, AdamW at 8e-4 with layer decay 0.94
Model 2: Mask2Former with the same backbone
Mask2Former uses a transformer decoder with 200 queries and a pixel decoder based on multi-scale deformable attention. Initialized from ADE20K weights (mask2former_flash_internimage_l_640_160k_ade20k_ss.pth) with manual handling of the 150 → 64 class mismatch. Training was slower per iteration (~2.1s vs ~0.9s) and stopped at ~47,000 iterations. Learning rate: 5e-5.
Augmentations
Standard MMSeg pipeline: random resize between 0.5x and 2.0x, random crop to 2048×1024, horizontal flip, photometric distortion, ImageNet normalization.
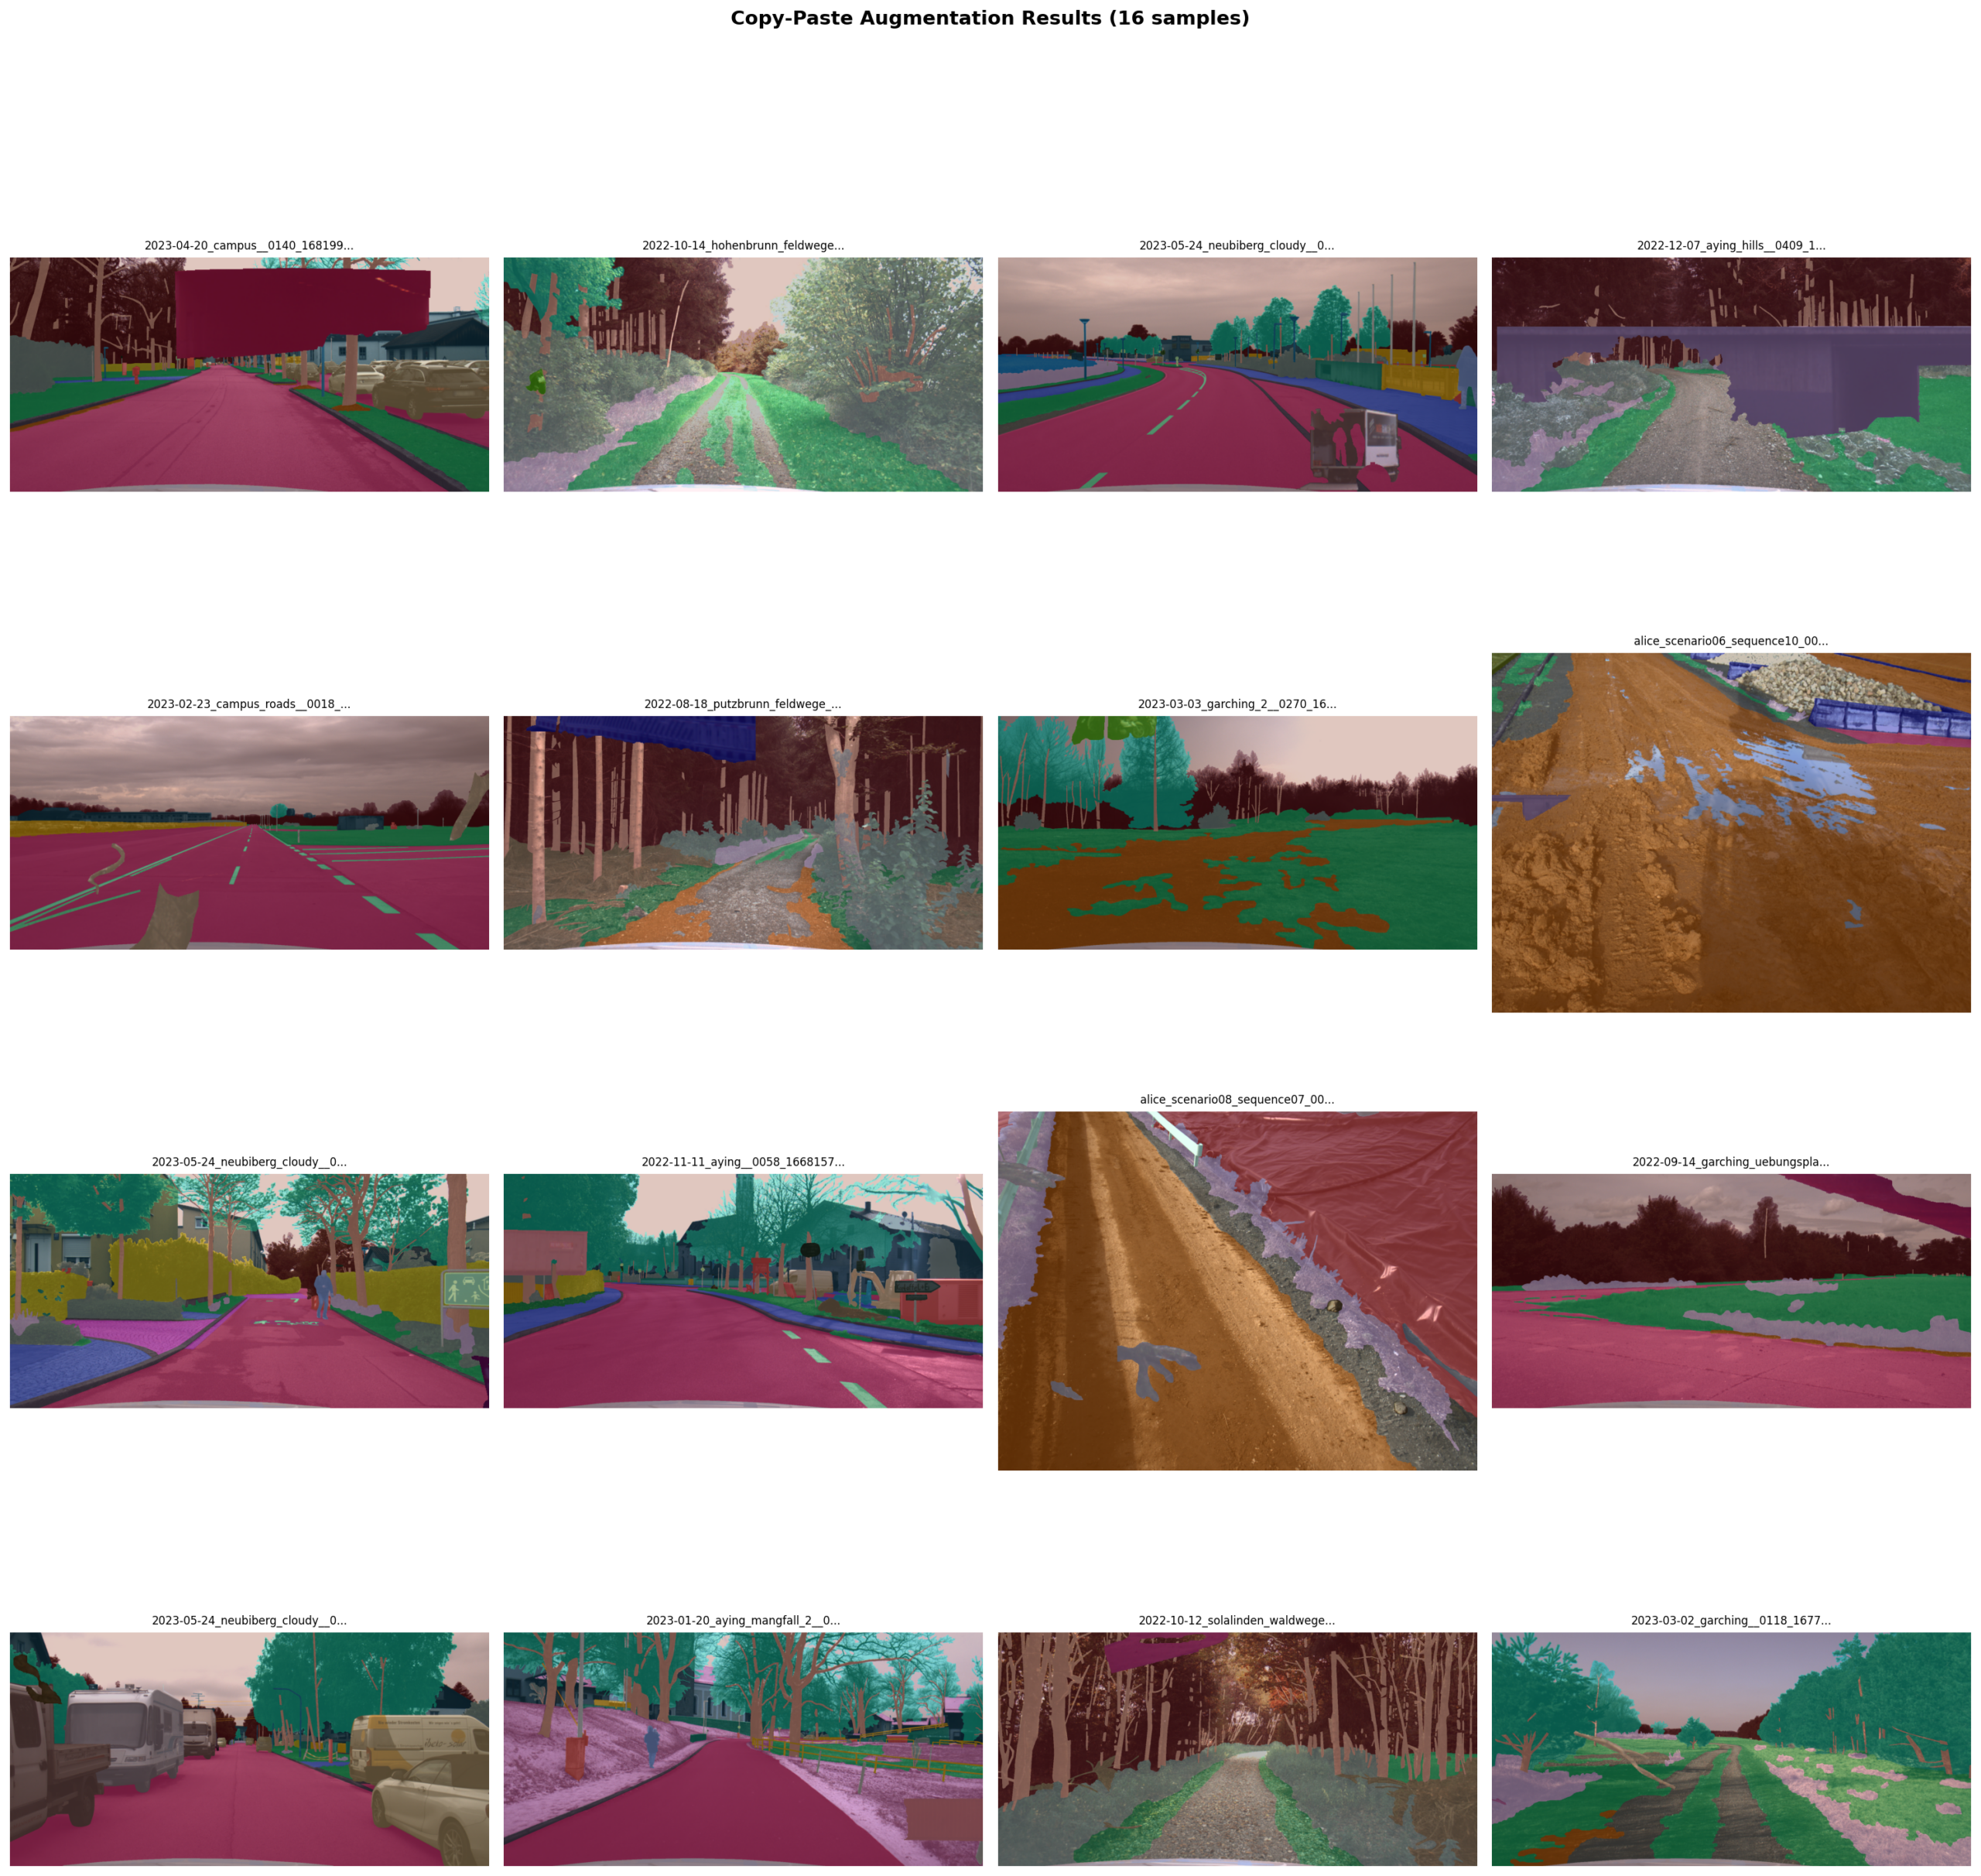
Copy-Paste: Instances of 17 rare classes extracted and pasted onto random target images with scaling from 0.2x to 4x. Two target images per source instance.

Class weighting: Both models used ENet-style weights: 1 / log(1.02 + frequency), normalized and scaled to 64.
Test-time augmentation
Multi-scale inference at [0.75, 1.0, 1.25, 1.5] with horizontal flipping.
Ensemble
Model 1 (UPerHead) outperformed Model 2 on validation: 51.71 % vs 46.85 % mIoU. M2 still won specific classes. street_light, for instance: M1 got 13.1 % IoU while M2 got 46.8 %.
Tuned rule ensemble: A 3D histogram H[m1_pred, m2_pred, ground_truth] built over the full validation set. For every pixel group where M1 predicts class i and M2 predicts class c, the question is whether overriding M1 with M2 improves mIoU. An atom is accepted only if:
- At least 500 pixels were in the group
- M2 was significantly more correct than M1 (precision margin 0.05)
- No single class dropped more than 0.005 IoU
- The gain exceeded 5e-5 on the validation set
The greedy search accepted 18 atoms across 10 rules. Examples:
- If M2 says
buildingand M1 saysobstacleorpole, trust M2 - If M2 says
curband M1 saysfence,gravel, orlow_grass, trust M2 - If M2 says
street_lightand M1 saysforestorpole, trust M2
M1 alone: 44.21 % mIoU on the tuning split. Tuned ensemble: 47.94 %. A +3.72 % gain from 18 pixel-level rules.
Training
Training ran on a single A100. M1 peaked around 58 GB memory. M2 was lighter at ~48 GB but slower.

M1 converged to higher mIoU and stayed there. M2’s loss looked reasonable but validation metrics plateaued lower. Mask2Former likely needs more data, longer training, or a better initialization than the ADE20K transfer. The transformer decoder also consumes many iterations.
Results
Validation metrics
| Approach | aAcc | mIoU | mAcc |
|---|---|---|---|
| UPerHead (M1) | 87.19 % | 51.71 % | 61.41 % |
| Mask2Former (M2) | 84.52 % | 46.85 % | 60.23 % |
| Tuned ensemble | 87.19 % | 51.79 % | 61.41 % |

The tuned ensemble edges out M1 by 0.08 % on validation. The real win is per-class. Some classes improved significantly.
Per-class IoU on validation
Top 30 classes by M1 IoU below. M1 dominates frequent classes like sky, asphalt, and forest. M2 is competitive on street_light, rider, and bicycle.

The scatter plot below shows log frequency against IoU for both models. Rare classes cluster near zero. sky sits alone at the top right. barrel is an outlier with high IoU despite low frequency because it has a consistent visual signature (yellow cylinders).

Radar chart
16 diverse classes spanning the frequency spectrum. M1 covers more area overall, but M2 bulges on street_light and bicycle.

Precision vs recall
Most points sit below the diagonal, meaning recall is the bottleneck. The model finds the class when it is present, but misses many pixels. sky and barrel are the exceptions — high precision, high recall, easy classes.

Error analysis
Confusion matrices
Row-normalized confusion for the top 20 frequent classes. Dark diagonals = good recall. Off-diagonal heat shows misclassification patterns.
Common misclassifications: tree_crown → forest, high_grass → low_grass, wall → building. The model struggles with fine-grained vegetation boundaries and architectural edges.
Model disagreement
M1 and M2 agree on 86.77 % of pixels. When they disagree, M1 wins 96 % of the time. The 4 % where M2 wins is where the ensemble gains come from.

Highest disagreement rates are on wall, rock, rider, and moss. These are ambiguous classes with fuzzy boundaries.

Ensemble gains
The waterfall chart below shows each accepted atom’s contribution to mIoU. Most atoms give small gains. A few give large gains — notably the debris → soil rule and the fence → curb rule.

Per-class IoU changes from the tuned rules. Biggest winners: curb (+55.3 %), debris (+23.5 %), street_light (+20.2 %). Some classes drop slightly, but the guard rails prevent any single class from dropping severely.

Qualitative results
Validation samples
Image, ground truth, M1, M2. M2 is visibly noisier on vegetation and road boundaries.


Test samples
No ground truth for the test set: image → M1 → M2 → tuned ensemble. The tuned rules shift predictions: building edges get cleaner, curb appears where M1 predicted fence, street_light appears where M1 predicted pole.


Official test results
The numbers above are from local validation. The official challenge test set evaluation is below. Composite mIoU: 63.80 %.
Per-class mIoU on test set
| ID | Class | mIoU (%) |
|---|---|---|
| 0 | undefined | 25.56 |
| 1 | traffic_cone | 0.00 |
| 2 | snow | 67.67 |
| 3 | cobble | 87.26 |
| 4 | obstacle | 53.99 |
| 5 | leaves | 19.74 |
| 6 | street_light | 49.20 |
| 7 | bikeway | 0.00 |
| 8 | ego_vehicle | 91.97 |
| 9 | pedestrian_crossing | 0.00 |
| 10 | road_block | 71.51 |
| 11 | road_marking | 72.07 |
| 12 | car | 93.73 |
| 13 | bicycle | 70.06 |
| 14 | person | 86.77 |
| 15 | bus | 87.79 |
| 16 | forest | 70.40 |
| 17 | bush | 38.97 |
| 18 | moss | 1.27 |
| 19 | traffic_light | 70.61 |
| 20 | motorcycle | 42.61 |
| 21 | sidewalk | 66.88 |
| 22 | curb | 63.23 |
| 23 | asphalt | 92.28 |
| 24 | gravel | 31.68 |
| 25 | boom_barrier | 35.35 |
| 26 | rail_track | 78.25 |
| 27 | tree_crown | 53.52 |
| 28 | tree_trunk | 65.07 |
| 29 | debris | 25.62 |
| 30 | crops | 77.21 |
| 31 | soil | 61.59 |
| 32 | rider | 44.85 |
| 33 | animal | 30.41 |
| 34 | truck | 51.78 |
| 35 | on_rails | 84.62 |
| 36 | caravan | 80.90 |
| 37 | trailer | 27.69 |
| 38 | building | 85.81 |
| 39 | wall | 54.83 |
| 40 | rock | 20.05 |
| 41 | fence | 84.46 |
| 42 | guard_rail | 62.40 |
| 43 | bridge | 7.62 |
| 44 | tunnel | 0.00 |
| 45 | pole | 50.44 |
| 46 | traffic_sign | 70.61 |
| 47 | misc_sign | 70.84 |
| 48 | barrier_tape | 27.02 |
| 49 | kick_scooter | 1.44 |
| 50 | low_grass | 73.01 |
| 51 | high_grass | 59.68 |
| 52 | scenery_vegetation | 33.35 |
| 53 | sky | 97.54 |
| 54 | water | 51.23 |
| 55 | wire | 31.55 |
| 56 | outlier | 0.00 |
| 57 | heavy_machinery | 48.78 |
| 58 | container | 59.42 |
| 59 | hedge | 48.98 |
| 60 | barrel | 92.30 |
| 61 | pipe | 0.00 |
| 62 | tree_root | 0.00 |
| 63 | military_vehicle | 0.00 |
Per-category mIoU
| Category | mIoU (%) |
|---|---|
| Animal | 30.41 |
| Construction | 78.37 |
| Human | 86.67 |
| Object | 40.42 |
| Road | 69.99 |
| Sign | 72.07 |
| Sky | 97.54 |
| Terrain | 89.14 |
| Vegetation | 93.39 |
| Vehicle | 86.77 |
| Water | 51.23 |
Overall
- mIoU fine: 55.24 %
- mIoU fine (coarse): 72.36 %
- mIoU composite: 63.80 %
The test gap between validation and test is notable. Some classes improved (cobble, road_block, trailer), others collapsed (leaves, moss, rock). The test set likely has different scene distributions or lighting conditions. The 0 % classes remained 0 %. traffic_cone and pipe probably need external data or synthetic injection to improve.
Repo structure
| File | What it does |
|---|---|
train_segment_py.py | Train UPerHead model. Full MMSeg config in Python. |
train_mask2former_l.py | Train Mask2Former. Handles ADE20K pretrained weights with class mismatch. |
generate_submission.py | Inference + submission packaging for UPerHead. |
generate_submission_mask2former.py | Inference + submission packaging for Mask2Former. |
ensemble_submission_tuned.py | Apply tuned_rules.py to test predictions. |
tune_ensemble_v2.py | Greedy rule optimizer. Builds 3D histogram, selects atoms. |
copypaste_augmentation.py | Copy-Paste augmentation for rare classes. |
copypaste_config.py | Config for Copy-Paste. |
Setup & Installation
Steps to go from a fresh machine to running training or inference.
1. Hardware
| Component | Minimum | Recommended |
|---|---|---|
| GPU | NVIDIA A100 80 GB | A100 80 GB or H100 |
| GPU memory (train) | ~58 GB (UPerHead), ~48 GB (Mask2Former) | 80 GB |
| Host RAM | 64 GB | 128 GB |
| Disk space | 400 GB free | 500 GB+ |
| CUDA capability | >= 8.0 (Ampere) | >= 8.0 |
Training ran on a single A100. The scripts are single-GPU. For inference only, a smaller GPU may work with reduced batch size or TTA disabled.
2. System dependencies
- CUDA >= 11.7 with matching NVCC and cuDNN
- GCC compatible with your CUDA (e.g. GCC 10–11 for CUDA 11.7)
- Standard build tools:
build-essential,git,wget
Check CUDA and NVCC:
nvidia-smi
nvcc --version
3. Python environment
Create the conda environment:
conda create -n dcnv4 python=3.10 -y
conda activate dcnv4
Install core deep-learning stack:
conda install pytorch torchvision pytorch-cuda=11.7 -c pytorch -c nvidia -y
Install OpenMMLab dependencies:
pip install -U openmim
mim install mmcv-full==1.5.0
mim install mmsegmentation==0.27.0
pip install timm==0.6.11 mmdet==2.28.1
Install remaining Python packages used by the scripts:
pip install opencv-python Pillow tqdm matplotlib scipy numpy pandas
4. Build the DCNv4 CUDA extension
The DCNv4 backbone requires a custom CUDA operator. It must be compiled from source: (The DCNv4 version in this repo is modified for compatibility with the current environment – A100 and newer cuda/python versions)
cd DCNv4/DCNv4_op
pip install -e .
If this fails, typical causes are:
CUDA_HOMEnot set:export CUDA_HOME=/usr/local/cuda- NVCC / GCC version mismatch
- PyTorch CUDA version does not match system CUDA
Verify the build:
python -c "import DCNv4.ext; print('OK')"
5. Prepare the data
The GOOSE and GOOSE-Ex datasets are downloaded automatically by the preparation script. They need ~192 GB of disk space.
python prepare_combined_dataset.py
This creates the expected data/ tree:
data/
  goose_2d_train/
  goose_2d_val/
  gooseEx_2d_train/
  gooseEx_2d_val/
  goose_2d_train_copypaste/   # created by copypaste_augmentation.py
  goose_label_mapping.csv
7. Optional: pretrained weights
Pretrained backbones are downloaded automatically on first run from HuggingFace:
- UPerHead backbone:
flash_intern_image_l_22kto1k_384.pth - Mask2Former pretrained:
mask2former_flash_internimage_l_640_160k_ade20k_ss.pth
To skip training and run inference only, download the best fine-tuned checkpoints and place them under checkpoints/goose_seg_dcnv4/ and checkpoints/goose_mask2former_l/.
Running things
The conda environment is dcnv4. Python 3.10, PyTorch, MMCV, MMSegmentation.
Train UPerHead:
conda run -n dcnv4 python train_segment_py.py > training.log 2>&1 &
Train Mask2Former:
conda run -n dcnv4 python train_mask2former_l.py > training_maskformer.log 2>&1 &
Generate validation predictions and submission:
conda run -n dcnv4 python generate_submission.py
conda run -n dcnv4 python generate_submission_mask2former.py
Tune the ensemble:
conda run -n dcnv4 python tune_ensemble_v2.py
conda run -n dcnv4 python ensemble_submission_tuned.py
Regenerate all README visuals:
conda run -n dcnv4 python generate_readme_visuals.py
conda run -n dcnv4 python generate_confusion_heatmap.py
conda run -n dcnv4 python generate_disagreement_chart.py
conda run -n dcnv4 python generate_pr_scatter.py
conda run -n dcnv4 python generate_test_side_by_sides.py
What worked and what didn’t
Worked:
- UPerHead decoder. Simple, reliable, better mIoU than Mask2Former for this data.
- Test-time augmentation. Reliable gains at no training cost.
- Class weighting. Stabilized training on the long tail.
- The tuned rule ensemble. +3.72 % mIoU from 18 atoms.
Didn’t work:
- Mask2Former underperformed given its compute cost. Likely needs longer training or better hyperparameter tuning. The ADE20K initialization may not transfer well to outdoor offroad scenes.
- Copy-Paste and oversampling helped a little, but could not fix the core issue: some classes have so few pixels that duplication does not create real signal.
- 64 classes is too many for the data volume. Several classes (
traffic_cone,pipe,tree_root,military_vehicle,kick_scooter) scored exactly 0.0 on test.
Not tried:
- Hard example mining / OHEM
- Boundary loss
- Pseudo-labeling on the test set
- Model distillation
- 3D point cloud fusion (the dataset has LiDAR)
- External datasets
